Introduction
A high-performance GPU cluster can provide the computing power needed for demanding workloads such as model training, large-scale inference, scientific computing, simulations, and data processing. However, building an effective cluster involves much more than connecting several GPUs. Hardware selection, networking, storage, scheduling, cooling, and software configuration all influence overall performance.
A carefully designed GPU cluster can help organizations scale workloads efficiently while making better use of expensive computing resources.
Steps of Building GPU Cluster
1. Choose the Right GPUs
The GPU is the foundation of the cluster. Different workloads have different requirements, so selecting hardware based on memory, compute performance, power consumption, and workload compatibility is essential.
High-end GPUs such as NVIDIA H100 and H200 can provide substantial computing capabilities for demanding workloads. However, organizations should consider whether they actually need the most powerful hardware or whether a different GPU configuration would provide better value.
2. Design High-Speed Networking
When multiple GPUs work together, communication between systems can become a performance bottleneck. A high-performance cluster therefore requires fast and reliable networking.
Technologies such as high-speed Ethernet and InfiniBand can support rapid data movement between compute nodes. RDMA can further reduce communication overhead by allowing data to move between systems with less CPU involvement. The networking architecture should be designed according to the scale and communication requirements of the workloads.
3. Build a Fast Storage Layer
GPU workloads can process large data-sets and model files, making storage performance another important consideration. Slow storage can leave expensive GPUs waiting for data. A cluster should have sufficient storage capacity as well as high read and write performance. NVMe-based storage can be useful for workloads requiring rapid access to frequently used data.
4. Implement Efficient Workload Scheduling
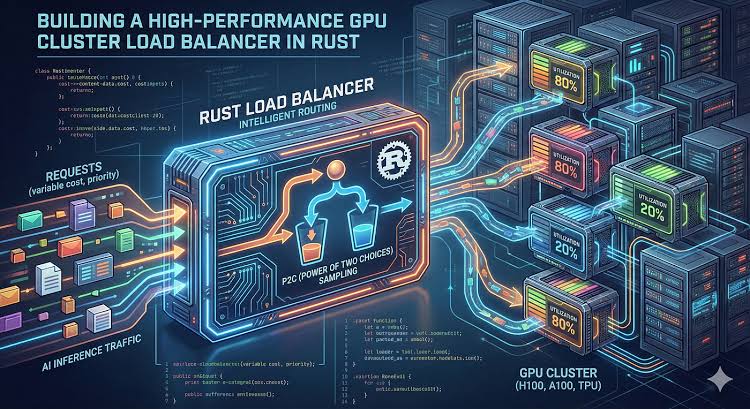
Simply having many GPUs does not guarantee efficient utilization. A scheduling system is needed to determine which resources should be assigned to different workloads. A good scheduler can consider GPU availability, memory requirements, workload priority, and resource allocation. This helps prevent some GPUs from being overloaded while others remain idle.
Dynamic resource allocation can further improve utilization by assigning computing resources according to changing demand.
5. Optimize the Software Environment
The software stack should be compatible with the selected GPUs and workloads. This may include operating systems, GPU drivers, CUDA libraries, container platforms, orchestration tools, and workload-specific frameworks.
Containerization can make deployments more consistent by packaging applications and their dependencies together. Orchestration platforms can also help teams manage workloads across multiple nodes.
6. Plan for Cooling and Power
High-performance GPUs can consume significant amounts of electricity and generate substantial heat. Cooling and power infrastructure must therefore be considered from the beginning.
Inadequate cooling can reduce hardware performance, increase failure risks, and shorten equipment lifespan. The cluster should have sufficient power capacity, airflow, and temperature management for both current and future hardware.
7. Monitor Cluster Performance
Monitoring is essential for maintaining a high-performance environment. Teams should track GPU utilization, memory usage, temperature, network performance, storage activity, and workload completion times. These metrics can reveal bottlenecks and help administrators identify underutilized resources.
Conclusion
Whether an organization builds its own cluster or uses managed cloud infrastructure, designing around actual workload requirements can help maximize GPU utilization, maintain consistent performance, and create an infrastructure foundation capable of scaling with future computing demands.